This page is in English.
How We Gave Away Control of Our IT
Article one in the BioJejak series on web security and encryption. A primer on why the series exists, before we get into how security and encryption actually work.
Why we are writing this series
Most conversations about web security start in the wrong place, with passwords, firewalls and which encryption to switch on. Those matter, and later articles in this series will cover them properly. But they sit on top of a deeper question that almost no one asks out loud: who actually controls your systems and your data? Over the last twenty years the honest answer, for most organisations, quietly changed from "we do" to "someone else does," and most of them never made a deliberate decision to let it happen. This first article tells that story, because you cannot reason about security until you know who holds the keys to the building.
BioJejak exists to track biomass and carbon data that people need to trust. That is only possible if we are clear-eyed about where data lives, who can reach it, and what we are prepared to run ourselves. This series is how we think about that in the open.
The on-premises era and why it ended
Into the 2000s, most organisations ran their own information technology. Servers sat in a room or a basement, the organisation owned the hardware, and a local team kept it running. Control was total and so was responsibility. The weakness was cost and effort, and the cost that moved fastest was software licensing.
As processors gained more cores, vendors moved to licensing that charged by the core or the socket, so the same physical server cost more to license with each hardware generation. Oracle's per-core database licensing, Microsoft SQL Server's shift to per-core pricing in 2012, and per-socket licensing for virtualisation platforms such as VMware all pushed on-premises software bills up sharply. Running your own servers increasingly meant writing ever-larger cheques to the same vendors for the right to keep using hardware you already owned. That economic squeeze, more than any technical failure of on-premises computing, is what made leaders willing to listen to an alternative.
The migration to the cloud
The alternative arrived in the mid-2000s. Salesforce had shown from 1999 that business software could be delivered over the web. Amazon Web Services launched its storage and compute services (S3 and EC2) in 2006, Microsoft Azure became generally available in 2010, and Office 365 followed in 2011. The pitch was compelling: stop buying and licensing hardware, rent capacity by the hour, turn a large capital expense (CapEx) into a smaller running cost (OpEx), and let someone else handle the plumbing. For finance teams that shift alone was often enough. Through the 2010s the default answer to any new IT question became "put it in the cloud."
What was actually traded away
The move was sold as a pure efficiency gain. In truth, three things were given up, and they were given up quietly.
- Control. Data and the systems that process it moved onto infrastructure the organisation does not own, cannot inspect, and operates only through a vendor's console. The physical location, the hardware, the underlying software and the provider's staff are all outside the customer's authority. Data you do not hold can ultimately be reached by anyone who can compel or compromise the party that does hold it, which is a sentence worth rereading if you handle anything sensitive.
- Resilience. A problem on your own servers is yours to fix on your own timeline. A problem in the cloud is the provider's to fix on theirs, and you wait. You have traded a problem you can act on for one you can only report.
- Accountability. When the systems live somewhere else, so does the blame. This is the part that is least discussed and matters most.
The outage problem
Depending on a shared provider means inheriting that provider's bad days, at a scale no single organisation would ever produce on its own. The public record is full of them. The February 2017 Amazon S3 outage in the us-east-1 region took down large parts of the web for hours. The June 2021 Fastly content-delivery outage briefly knocked out major news and government sites worldwide. A Facebook configuration error in October 2021 removed its own services from the internet for most of a day. The December 2021 AWS us-east-1 disruptions cascaded through countless dependent businesses. In every case the affected customers could do nothing but wait for someone else's engineers. The July 2024 CrowdStrike update that grounded airlines and disrupted hospitals was a different mechanism, a faulty vendor update rather than a cloud outage, but it taught the same lesson: when one outside dependency fails, everyone who leaned on it fails together.
The hacking problem
Outages are the visible failure. The quieter one is intrusion, and the record here is far worse. Over the past decade an extraordinary number of large organisations and government systems have been breached, very often the big centralised ones that held the most data. The United States Office of Personnel Management lost around 21.5 million security-clearance background files, fingerprints included, in a breach disclosed in 2015. The credit bureau Equifax lost data on about 147 million people in 2017. The Marriott and Starwood hotel group disclosed in 2018 that up to roughly 383 million guest records had been exposed. The health insurer Anthem lost around 78.8 million records in 2015, and in Australia, Medibank (around 9.7 million) and Optus (around 9.8 million) were both breached in 2022. Yahoo remains the extreme case, with all three billion of its accounts compromised in breaches revealed in 2017. This is not a list of rare disasters; it is closer to the norm.
Two things about this record are usually glossed over, and both matter here.
First, the attribution. Many of these intrusions were publicly blamed on China, among them OPM, Equifax, Anthem and Marriott, and in some cases a government backed the claim with criminal indictments. But attribution in cyberspace is inference, not proof. It is pieced together from malware traits, server infrastructure, language fragments and timing, all of which can be copied, reused or deliberately planted, and a confident public naming of a foreign state is sometimes as much about politics and deflection as about evidence. Blaming a distant superpower is convenient: it reframes a breach as an act of war that no defender could have stopped, rather than a lapse someone should answer for. And when the facts came out, the cause was often far more ordinary than a foreign intelligence service. The Capital One breach of 2019, about 106 million people, was not a nation-state at all; it was a single individual, a former cloud-provider engineer, exploiting a misconfigured firewall in front of data stored in the cloud. "Was it really China?" is a fair question to ask of almost every headline, and the honest answer is often "we are inferring, and sometimes it was something much closer to home."
Second, the promises. Almost every one of these systems launched with assurances of total data security, of modern, robust, effectively unhackable protection. There is no such thing. No system is unhackable, and treating "secure" as a finished state rather than a continuous effort is itself part of the failure. The ending is monotonous: the data that was promised to be safe is copied out, and sooner or later it is offered for sale on criminal marketplaces on the dark web, or, when a ransom is refused, simply dumped in public, as happened with the Medibank records in 2022. Once data leaves your control you cannot get it back, and no apology re-seals it.
The thread back to this article's argument is direct. The more data you concentrate on systems you do not control, the larger and more valuable the target you create, and the less you can do about it when, not if, someone gets in.
The accountability problem
Here is the uncomfortable part. The cloud does not only move the technology off-site, it moves the responsibility off the IT department's desk. When a big provider goes down, the IT manager has a ready answer: it was not us, it was the provider. That is a powerful thing to be able to say, and it changes behaviour. A manager who can never be blamed for an outage has less reason to engineer against one. Providers even formalised this with the "shared responsibility model," which in practice draws a tidy line with the customer on the comfortable side of it for anything infrastructural.
So the cloud quietly offers two conveniences that have nothing to do with technology. It gives an IT function an excuse to do a mediocre job, because the hardest failures are now someone else's fault. And it gives leadership a reason never to reconsider, because reversing course means taking the responsibility back. Outsourcing the systems outsources the accountability, and an organisation that cannot be blamed for a failure rarely invests in preventing it. That is how a cost-driven decision from the 2000s hardened into a posture no one revisits.
Concentration and systemic risk
What began as many individual choices has become a structural problem. A large share of the internet now runs on a handful of providers, and regulators have started to treat that concentration as a risk in its own right. The European Union's Digital Operational Resilience Act (DORA), which came into application in January 2025, brings critical third-party technology providers, cloud providers above all, under direct oversight precisely because the failure of one could threaten the stability of entire sectors. When the supervisor of the financial system is worried about who hosts the financial system, the loss of control has stopped being a private matter.
The counter-current: owning hardware again
The movement is not all one way, and this is worth stating so the argument does not read as nostalgia. Organisations with the scale and skill to do the arithmetic have moved workloads back. Dropbox built its own storage infrastructure and largely left Amazon's cloud from 2016, reporting large savings. The software company 37signals (Basecamp) publicly left the cloud across 2022 and 2023, bought its own servers, and reported expected savings on the order of millions of dollars over several years. And when Broadcom acquired VMware in 2023 and moved it to subscription licensing with steep price rises through 2024, it reminded everyone that the licensing economics which once pushed organisations into the cloud can just as easily turn against them there. Owning your own hardware is not a relic. For the right workloads it is again the rational choice.
The rule for the things that matter most
For ordinary, low-sensitivity, bursty workloads, the cloud is a reasonable tool, and this article is not an argument against it everywhere. The argument is narrower and firmer. If a system is genuinely mission-critical, if safety, trust, continuity of operations or irreplaceable data depend on it, then renting it is not good enough. Control of a mission-critical system means control of its physical layer, its failure modes and its recovery, and you cannot have that over infrastructure you do not own. Telecommunications carriers, stock exchanges, defence networks and utilities have always known this and run their own core infrastructure for exactly this reason. The discipline is simple to state: own the hardware, own the physical path, and keep the parts you cannot afford to lose under your own hand.
A practitioner's note: the black fibre argument
The principle is easier to hold in the abstract than to win in a meeting. On one project I was responsible for a link that was genuinely mission-critical. The IT department wanted to provision it as a managed service over rented, shared provider infrastructure, because it was cheaper and it was the default. I argued that a mission-critical link cannot sit on infrastructure we neither own nor control, and that it needed to run over black fibre: a dedicated, unlit optical strand that we light with our own equipment and control end to end, rather than a managed service riding shared provider plant. Dedicated fibre gives you control of the physical path, no shared tenancy on the strand, and a link you can encrypt end to end over ground you hold. The managed service gives you a monthly bill and someone else's priorities. I made the case that for this link the physical layer itself was part of the security boundary, and I won the argument. The lesson generalises: the cheap, rented, shared option will always be the default, and for the things that matter it is worth the fight to own the path.
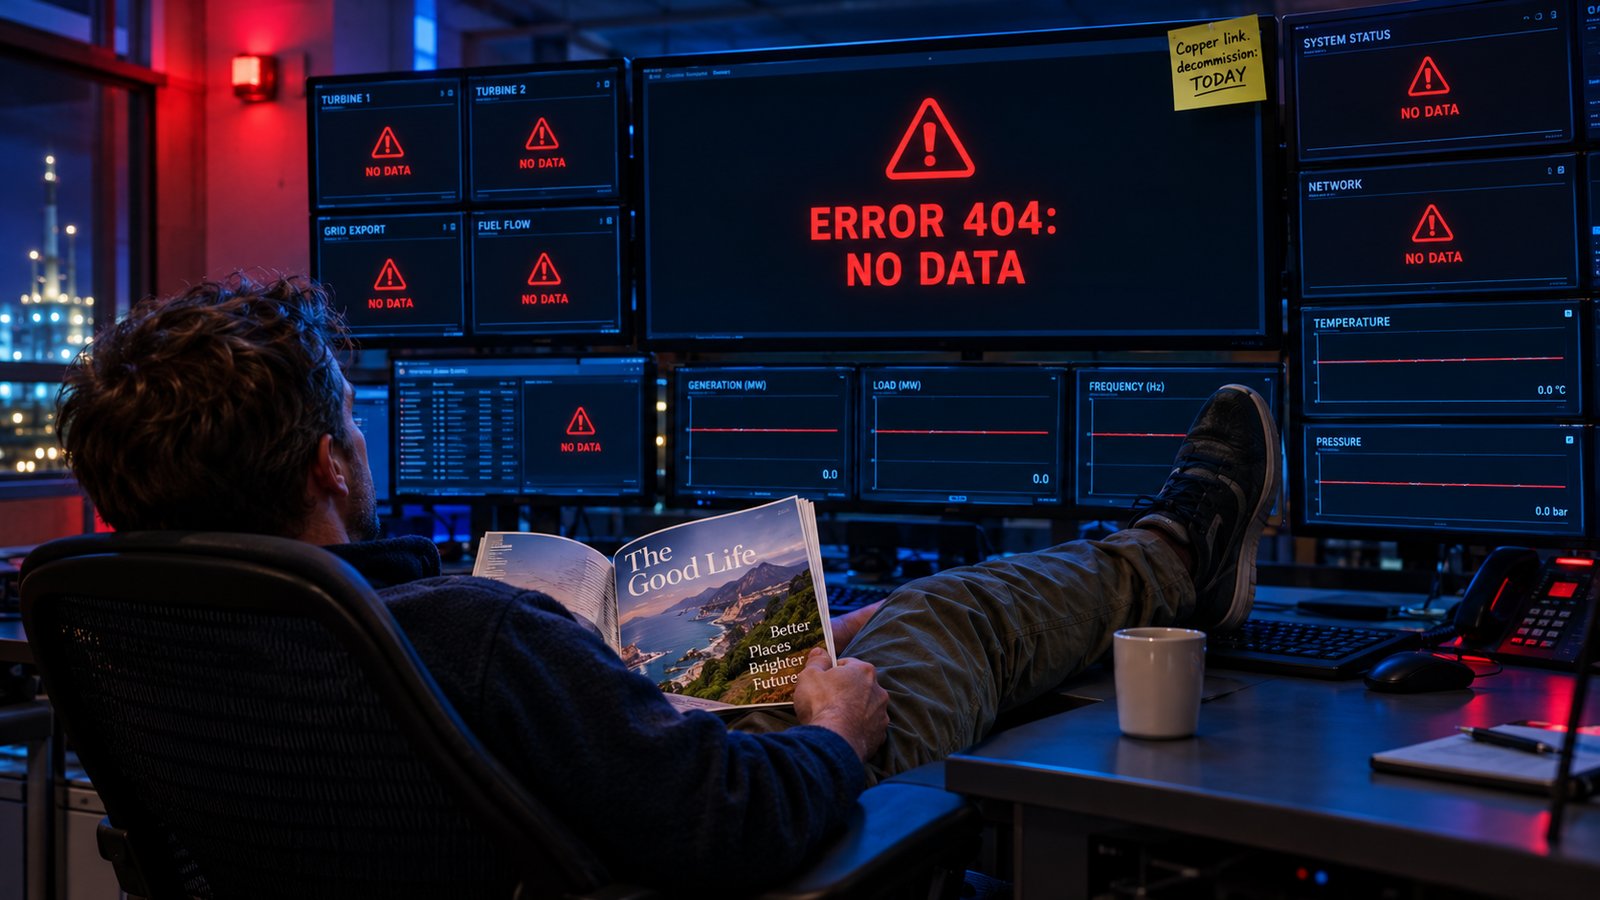
I have seen the opposite failure just as clearly. In another case, mission-critical telemetry for a piece of national infrastructure was still running over rented legacy cabling: copper laid some sixty years earlier, carrying data at a trickle of bandwidth. The provider gave formal notice that the old copper would be decommissioned by a set date. For one reason or another the organisation let the notice slide behind the couch, on the unspoken assumption that if the problem was ignored long enough the link would somehow stay up. The day of reckoning arrived on schedule. The legacy telemetry went dark, the control room display went blank, and there was no data at all. Panic. A migration that had been nobody's priority for years became the top priority overnight. The lesson is the mirror image of the first: when your critical systems ride on infrastructure you do not own, you do not control their lifecycle either, and a provider's decommissioning date is not a suggestion you can wish away. Owning the path is not only about security and resilience in the moment, it is about not letting someone else decide when your system stops existing.
What this series will cover
Hold one idea from this article as the series continues: security is not only a set of features you switch on, it is a question of who controls the ground your systems stand on. From that foundation the next articles get practical. We will look at what encryption actually does and where it protects you (in transit and at rest), what it does not do on its own, how keys are generated and kept, how to think about the real threats to a platform rather than the imaginary ones, and where it makes sense to own infrastructure rather than rent it. The goal is not fear. It is to help you make deliberate choices about your own systems, the choices that, as this article has argued, most organisations never consciously made at all.
Comments
No comments yet.